NEC Laboratories America
Link to: Media Analytics
MEDIA ANALYTICS
PROJECTS
Link to: MA People
PEOPLE
Link to: MA Publications
PUBLICATIONS
Link to: MA Patents
PATENTS
MM-TTA: Multimodal Test-Time Adaptation for 3D Sematic Segmentation
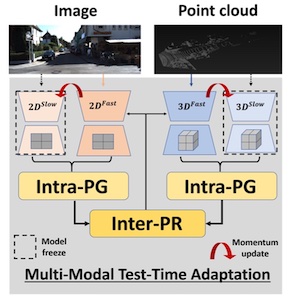
We propose a Multi-Modal Test-Time Adaptation (MM-TTA) framework that enables a model to be quickly adapted to multi-modal test data without access to the source domain training data. We introduce two modules: 1) Intra-PG to produce reliable pseudo labels within each modality via updating two models (batch norm statistics) in different paces, i.e., slow and fast updating schemes with a momentum, and 2) Inter-PR to adaptively select pseudo-labels from the two modalities. These two modules seamlessly collaborate with each other and co-produce final cross-modal pseudo labels to help test-time adaptation.
Collaborators: Sparsh Garg
Paper
Inkyu Shin1 Yi-Hsuan Tsai2 Bingbing Zhuang3 Samuel Schulter3
Buyu Liu3 Sparsh Garg3 In So Kweon1 Kuk-Jin Yoon1
Buyu Liu3 Sparsh Garg3 In So Kweon1 Kuk-Jin Yoon1
1 KAIST 2 Phiar 3 NEC Laboratories America
CVPR 2022
  @inproceedings{mmtta_cvpr_2022,
    author = {Inkyu Shin and Yi-Hsuan Tsai and Bingbing Zhuang and Samuel Schulter
              and Buyu Liu and Sparsh Garg and In So Kweon and Kuk-Jin Yoon},
    title = {{MM-TTA}: Multi-Modal Test-Time Adaptation for 3D Semantic Segmentation},
    booktitle = {CVPR},
    year = 2022
  }
Abstract
Test-time adaptation approaches have recently emerged as a practical solution for handling domain shift without access to the source domain data. In this paper, we propose and explore a new multi-modal extension of test-time adaptation for 3D semantic segmentation. We find that directly applying existing methods usually results in performance instability at test time because multi-modal input is not considered jointly. To design a framework that can take full advantage of multi-modality, where each modality provides regularized self-supervisory signals to other modalities, we propose two complementary modules within and across the modalities.
Short Summary of MM-TTA Process
Main Results
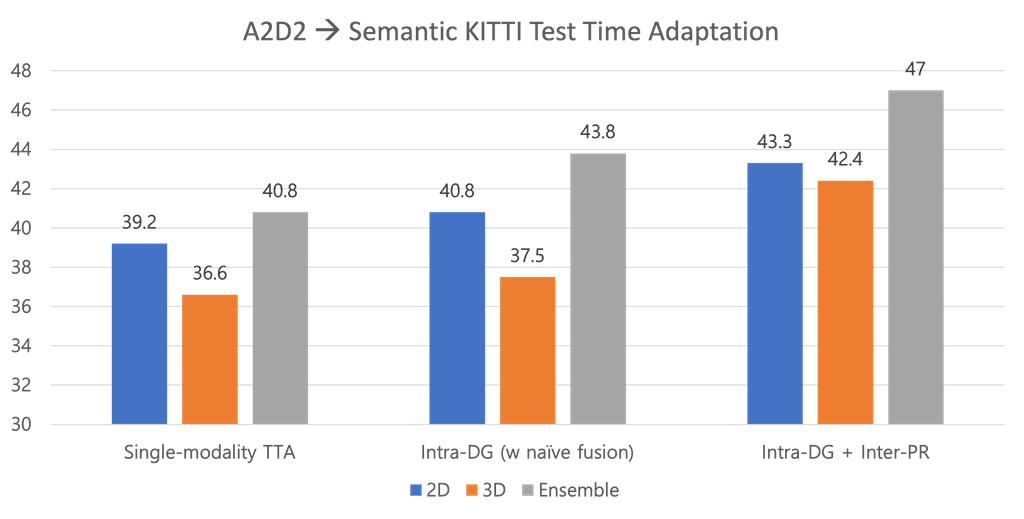
3D semantic segmentation results (mIoU) for different methods (Single-modality TTA, Intra-DG (w/ naive fusion), and Inter-DG + Inter-PR) on the A2D2 → SemanticKITTI benchmark. The different bars for each method show the 2D, 3D and ensemble predictions.
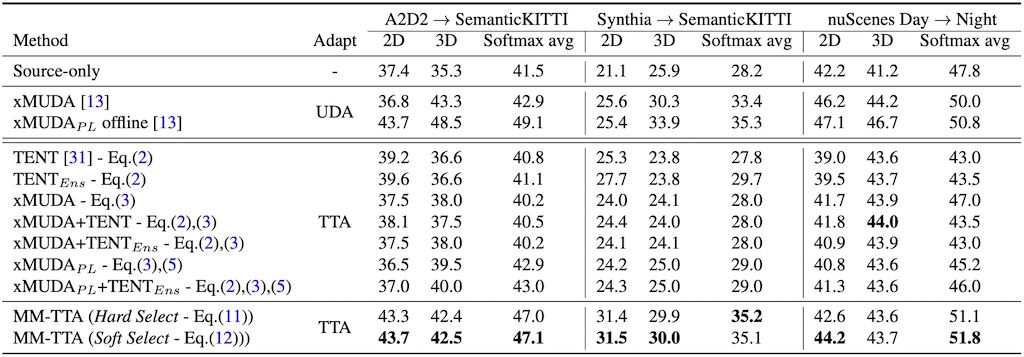
Quantitative comparisons of our MM-TTA approach with UDA methods and TTA baselines for multi-modal 3D semantic segmentation in three settings (A2D2 → SemanticKITTI, Synthia → SemanticKITTI, and nuScenes Day → Night).
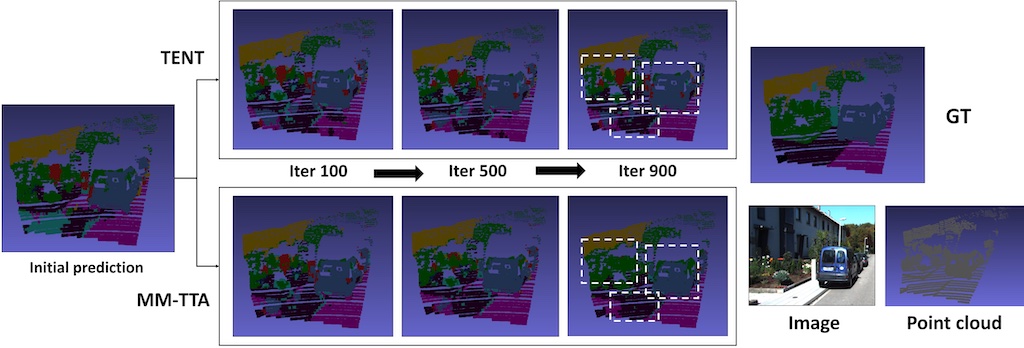
Example results of our MM-TTA during test-time adaptation for gradual improvement. While TENT shows little improvements during adaptation, our method can effectively suppress the noise and achieve visually similar results to the ground truth, especially within the area of dotted white boxes.