NEC Laboratories America

Domain Adaptation for Structured Output via Discriminative Patch Representations | Projects

PROJECTS

Domain Adaptation for Structured Output via Discriminative Patch Representations

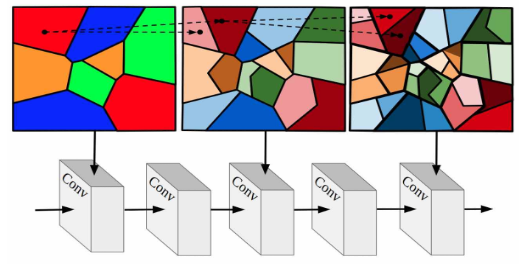
We tackle domain adaptive semantic segmentation via learning discriminative feature representations of patches in the source domain by discovering multiple modes of patch-wise output distribution through the construction of a clustered space. With such guidance, we use an adversarial learning scheme to push the feature representations of target patches in the clustered space closer to the distributions of source patches. We show that our framework is complementary to existing domain adaptation techniques.

Collaborators: Yi-Hsuan Tsai, Kihyuk Sohn, Manmohan Chandraker

Domain Adaptation for Structured Output via Discriminative Patch Representations

Project Data

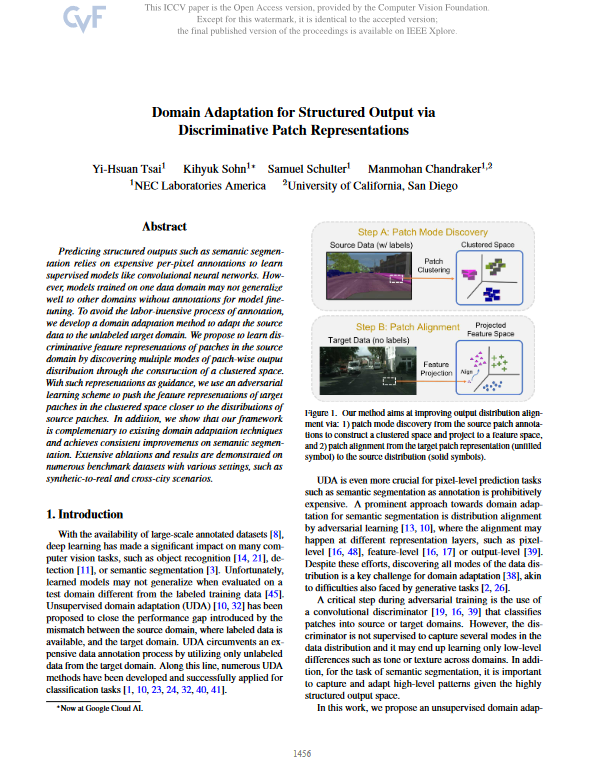
Our method aims at improving output distribution alignment via: 1) patch mode discovery from the source patch annotations to construct a clustered space and project to a feature space, and 2) patch alignment from the target patch representation (unfilled symbol) to the source distribution (solid symbols). Predicting structured outputs such as semantic segmentation relies on expensive per-pixel annotations to learn supervised models like convolutional neural networks. However, models trained on one data domain may not generalize well to other domains unequipped with annotations for model fine-tuning. To avoid the labor-intensive process of annotation, we develop a domain adaptation method to adapt the source data to the unlabeled target domain. To this end, we propose to learn discriminative feature representations of patches in the source domain via discovering multiple patch modes through the construction of a clustered space. With such representations as guidance, we then use an adversarial learning scheme to push the feature representations in target patches to the closer distributions in source ones. In addition, we show that our framework is complementary to existing domain adaptation techniques and achieves consistent improvements on semantic segmentation. Extensive ablation studies and experiments are conducted on numerous benchmark datasets with various settings, such as synthetic-to-real and cross-city scenarios.
Domain Adaptation for Structured Output via Discriminative Patch Representations Paper

1 NEC Laboratories America 2 Google Cloud AI 3 UC San Diego

In IEEE International Conference on Computer Vision (ICCV) 2019 (Oral)

[Download Paper] [Paper at Arxiv]

Abstract

Predicting structured outputs such as semantic segmentation relies on expensive per-pixel annotations to learn supervised models like convolutional neural networks. However, models trained on one data domain may not generalize well to other domains without annotations for model fine-tuning. To avoid the labor-intensive process of annotation,we develop a domain adaptation method to adapt the source data to the unlabeled target domain. We propose to learn discriminative feature representations of patches in the source domain by discovering multiple modes of patch-wise output distribution through the construction of a clustered space. With such representations as guidance, we use an adversarial learning scheme to push the feature representations of target patches in the clustered space closer to the distributions of source patches. In addition, we show that our framework is complementary to existing domain adaptation techniques and achieves consistent improvements on semantic segmentation. Extensive ablations and results are demonstrated on numerous benchmark datasets with various settings, such as synthetic-to-real and cross-city scenarios.
Domain Adaptation for Structured Output via Discriminative Patch Representations

Dataset of Oxford RobotCar


Video Results on Cityscapes-to-Oxford

Domain Adaptaption Publications

Position Really Matters: Towards a Holistic Approach for Prompt Tuning

Prompt tuning is highly effective in efficiently extracting knowledge from foundation models, encompassing both language, vision, and vision-language models. However, the efficacy of employing fixed soft prompts with a predetermined position for concatenation with inputs for all instances, irrespective

Text-guided Device-realistic Sound Generation for Fiber-based Sound Event Classification

Recent advancements in unique acoustic sensing devices and large-scale audio recognition models have unlocked new possibilities for environmental sound monitoring and detection. However, applying pretrained models to non-conventional acoustic sensors results in performance degradation due to domain shifts,

POND: Multi-Source Time Series Domain Adaptation with Information-Aware Prompt Tuning

Time series domain adaptation stands as a pivotal and intricate challenge with diverse applications, including but not limited to human activity recognition, sleep stage classification, and machine fault diagnosis. Despite the numerous domain adaptation techniques proposed to tackle this complex problem,

Source-Free Domain Adaptive Fundus Image Segmentation with Class-Balanced Mean Teacher

This paper studies source-free domain adaptive fundus image segmentation which aims to adapt a pretrained fundus segmentation model to a target domain using unlabeled images. This is a challenging task because it is highly risky to adapt a model only using unlabeled data. Most existing methods tackle

Towards Realizing the Value of Labeled Target Samples: a Two-Stage Approach for Semi-Supervised Domain Adaptation

Semi-Supervised Domain Adaptation (SSDA) is a recently emerging research topic that extends from the widely-investigated Unsupervised Domain Adaptation (UDA) by further having a few target samples labeled, i.e., the model is trained with labeled source samples, unlabeled target samples as well as a few

Adversarial Alignment for Source Free Object Detection

Source-free object detection (SFOD) aims to transfer a detector pre-trained on a label-rich source domain to an unlabeled target domain without seeing source data. While most existing SFOD methods generate pseudo labels via a source-pretrained model to guide training, these pseudo labels usually contain

Learning Cross-Modal Contrastive Features for Video Domain Adaptation

Learning transferable and domain adaptive feature representations from videos is important for video-relevant tasks such as action recognition. Existing video domain adaptation methods mainly rely on adversarial feature alignment, which has been derived from the RGB image space. However, video data is

Domain Adaptive Semantic Segmentation using Weak Labels

We propose a novel framework for domain adaptation in semantic segmentation with image-level weak labels in the target domain. The weak labels may be obtained based on a model prediction for unsupervised domain adaptation (UDA), or from a human oracle in a new weakly-supervised domain adaptation (WDA)

Shuffle and Attend: Video Domain Adaptation

We address the problem of domain adaptation in videos for the task of human action recognition. Inspired by image-based domain adaptation, we can perform video adaptation by aligning the features of frames or clips of source and target videos. However, equally aligning all clips is sub-optimal as not

Active Adversarial Domain Adaptation

We propose an active learning approach for transferring representations across domains. Our approach, active adversarial domain adaptation (AADA), explores a duality between two related problems: adversarial domain alignment and importance sampling for adapting models across domains. The former uses

Unsupervised and Semi-Supervised Domain Adaptation for Action Recognition from Drones

We address the problem of human action classification in drone videos. Due to the high cost of capturing and labeling large-scale drone videos with diverse actions, we present unsupervised and semi-supervised domain adaptation approaches that leverage both the existing fully annotated action recognition

Domain Adaptation for Structured Output via Discriminative Patch Representations

Predicting structured outputs such as semantic segmentation relies on expensive per-pixel annotations to learn supervised models like convolutional neural networks. However, models trained on one data domain may not generalize well to other domains without annotations for model finetuning. To avoid the

Unsupervised Domain Adaptation for Distance Metric Learning

Unsupervised domain adaptation is a promising avenue to enhance the performance of deep neural networks on a target domain, using labels only from a source domain. However, the two predominant methods, domain discrepancy reduction learning and semi-supervised learning, are not readily applicable when